
Evidence date · 2024-03-08 · Research note 1 of 3
1 2 3
See current Track status →
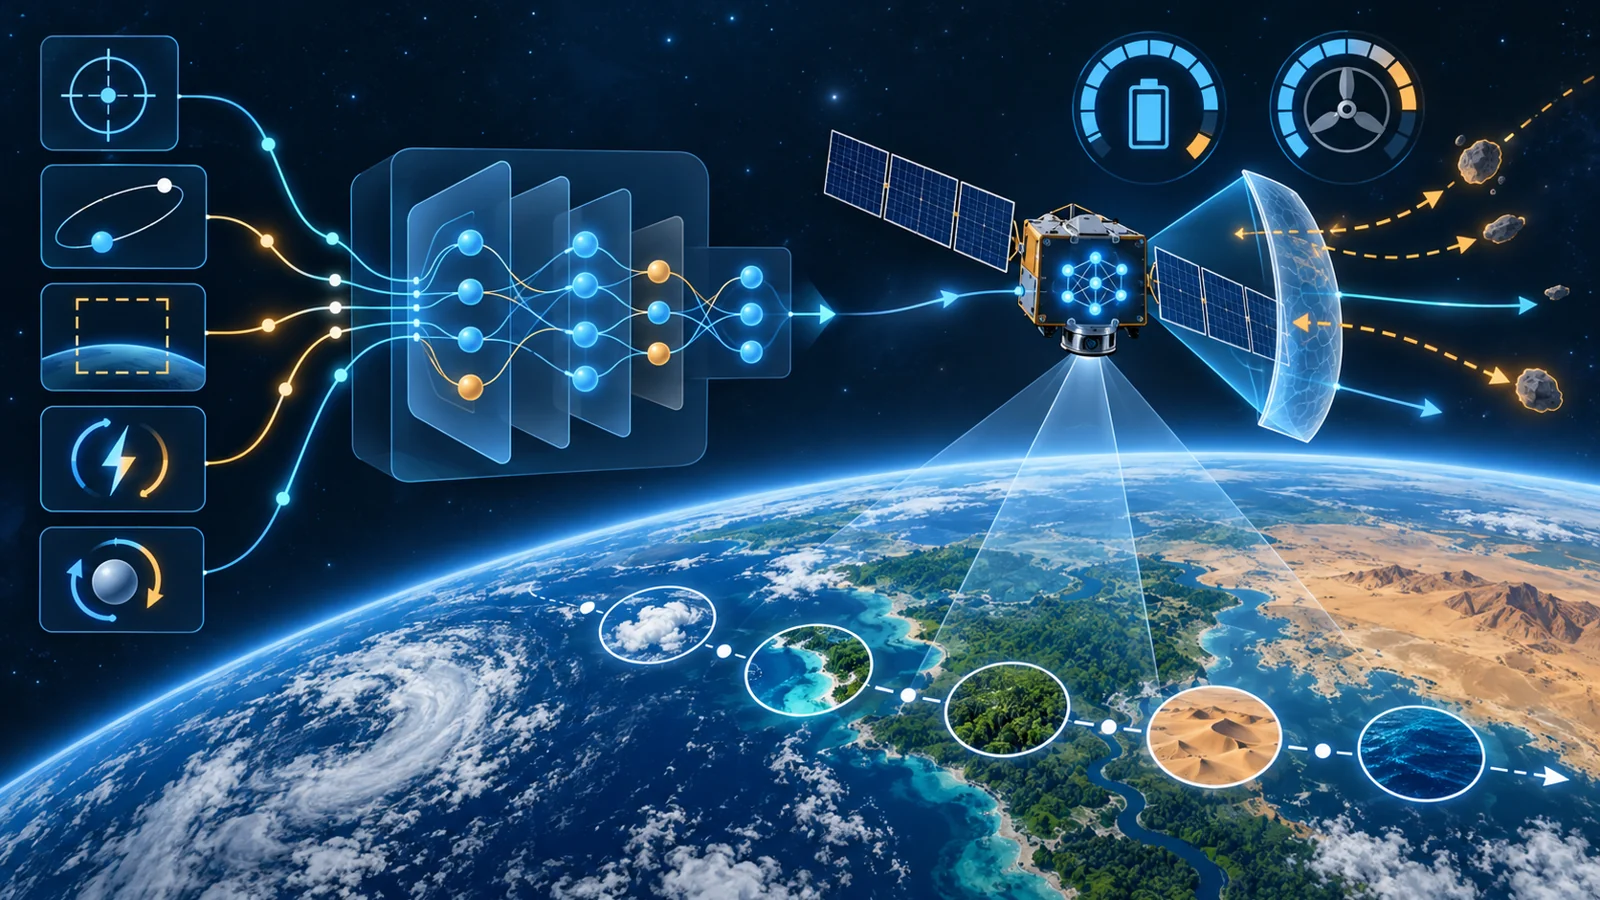
A spacecraft asked to image Earth is not simply choosing the next interesting target. It must carry out an ordered assignment while preserving the operating conditions that keep the vehicle usable. Power must remain above a safe floor, and reaction-wheel speeds must stay within their allowed range. A learning system therefore faces two demands at once: complete the task and avoid actions that could push the spacecraft beyond its limits.
A March 8, 2024 arXiv preprint, Shielded Deep Reinforcement Learning for Complex Spacecraft Tasking, studies that combination in simulation. Its approach joins formal descriptions of imaging tasks with safety-aware reinforcement learning and model-based shields. The result is a more precise way to ask whether a policy can learn a complicated assignment, while also making clear what a modeled safety guarantee does and does not cover.
A mission plan becomes a sequence of rules
The researchers use Linear Temporal Logic, or LTL, to describe both what the spacecraft should eventually accomplish and what it must avoid throughout the assignment. These are different kinds of requirements. A task rule may specify an ordered series of imaging actions. A safety rule may require the spacecraft to remain above a power threshold or below a wheel-speed threshold at every relevant step.
That separation matters because reinforcement learning usually needs a reward signal. If the reward is too sparse, the system may receive useful feedback only after completing a long sequence, making it difficult to identify which choices helped. The preprint describes a way to construct a reward automatically from a co-safe LTL task specification. The goal is to preserve the structure of the assignment instead of relying on an informal human interpretation of what counts as progress.
One example makes the challenge concrete. The spacecraft must complete five images using alternating imaging modes, while also satisfying safety requirements. The assignment is not just a list of independent targets. It has order and mode changes that the learned policy must coordinate with the vehicle’s state. Formalizing those conditions gives training a representation of the intended sequence rather than a single end-of-task signal.
The same formal approach also supplies the safety side of the problem. The authors investigate how a shield can be built from a safe LTL specification, proposing three designs with probabilistic guarantees within a simulated safety model.
Sparse rewards made the ordered task harder to learn
In the complex five-image benchmark, the original reward formulation led to spacecraft failure in 38.9% of simulated trajectories. The authors’ modified formulation reduced the reported failure rate to 1.4% when training used the same number of epochs.
The comparison is about learning efficiency under a fixed training budget, not a universal score for spacecraft autonomy. The important difference is how much guidance the reward provides while the policy is learning the sequence. With the original formulation, the reward can be too sparse for a complicated specification. A policy may spend the available training time without receiving enough informative feedback to discover a reliable route through the assignment.
By constructing the reward from the formal task description, the modified formulation makes progress through the required sequence more useful to learning. The large gap in this study therefore illustrates a specific mechanism: a clearer connection between the ordered task and the reward can reduce failures in the simulated training comparison.
The result also shows why task definition is part of the control problem. A policy cannot be evaluated only on whether it eventually produces an image. It must satisfy the required order and imaging modes while remaining compatible with the spacecraft’s operating state. Encoding those conditions explicitly gives the experiment a way to measure whether the learned behavior matches the assignment it was meant to perform.
Learning and shielding play different roles
A shield is an additional protection mechanism, but it is not the same thing as including safety in the learning objective. During operation, a shield can constrain the policy’s available actions according to the modeled safety requirements. During training, however, the researchers can choose whether shield interventions occur while the policy is learning.
The preprint reports its best policy–shield interaction when training included composed task-completion and safety specifications but did not use a shield to intervene during training. In the reported evaluations, this setup produced a high rate of task satisfaction, few safety violations and few shield interventions once the policy interacted with the shield.
Safety requirements can therefore shape the training objective even when the shield does not intervene during training. The reported evaluations favor that combination, but the comparison alone does not establish why it produced the best policy–shield interaction.
The study’s safety constraints were specific: the shields were designed to prevent power from falling below 20% and reaction-wheel speeds from rising above 80%. Those thresholds define the experiment’s operating envelope. They should not be read as general limits for every spacecraft or mission.
The guarantee belongs to a safety model
The proposed shields provide probabilistic guarantees inside a safety Markov decision process. In plain terms, the guarantee depends on a model of how the spacecraft can move between states and how likely those transitions are. In this work, the transition probabilities were estimated through a physics simulator.
That dependency is central. A guarantee within the safety model is not an unconditional guarantee that a physical spacecraft will always remain safe. The simulator must represent the relevant behavior well enough for the modeled probabilities to support the conclusion. The authors identify further formalization of the safety model as future work, along with reducing the conservatism introduced by the shielding approach.
Conservatism here is a design tradeoff. A shield that rules out more actions may provide a wider margin inside its model, but it can also restrict the policy more than necessary. The authors report that their shields were less restrictive than prior designs discussed in the paper, while numerical simulations suggested that the guarantees were stronger than necessary. That observation points to a more flexible controller, but it does not convert the simulation into flight validation.
The March 2024 study therefore establishes a focused milestone in simulated spacecraft tasking. It combines formal imaging requirements, automatically constructed rewards and model-based safety shields, then tests how those pieces interact. The evidence supports the value of that combination for the study’s scenarios. It does not establish deployment on an operating spacecraft, performance across arbitrary hardware or missions, or a measured mission-level benefit.
Why this matters for autonomous Earth imaging
The practical possibility is richer delegation of Earth-imaging assignments. A spacecraft could eventually receive an ordered sequence of imaging requests and learn how to carry it out while respecting power and reaction-wheel limits, rather than requiring every action to be specified in advance.
That capability remains conditional on the learned task performance and modeled protection transferring reliably to operational spacecraft. If those bottlenecks are resolved, mission teams could have more flexibility in the assignments they delegate to an autonomous vehicle, including tasks that require several images and changing imaging modes while the spacecraft stays within its operating limits.
Key Sources
- Primary source: Shielded Deep Reinforcement Learning for Complex Spacecraft Tasking
arXiv · Preprint · 2024-03-08