
Evidence date · 2026-08-25 · Research note 3 of 3
1 2 3
See current Track status →
Since the previous research note · Earlier expectation not tested
Track continuity
Since the previous research note: From a satellite assignment to a checked computing workflow
Previous expectation: Mission teams could gain a more dependable, inspectable route from authored assignments to onboard computing workflows if runtime integration and mission-specific checks proved reliable.
What this study adds: The August 25, 2026 preprint reports a learning-guided search method for observation schedules, with improved weighted utility across six constructed mixed-satellite scenarios. Its evidence addresses task allocation and sequencing, not compiler integration or acceptance-policy checks.
What changed in this study
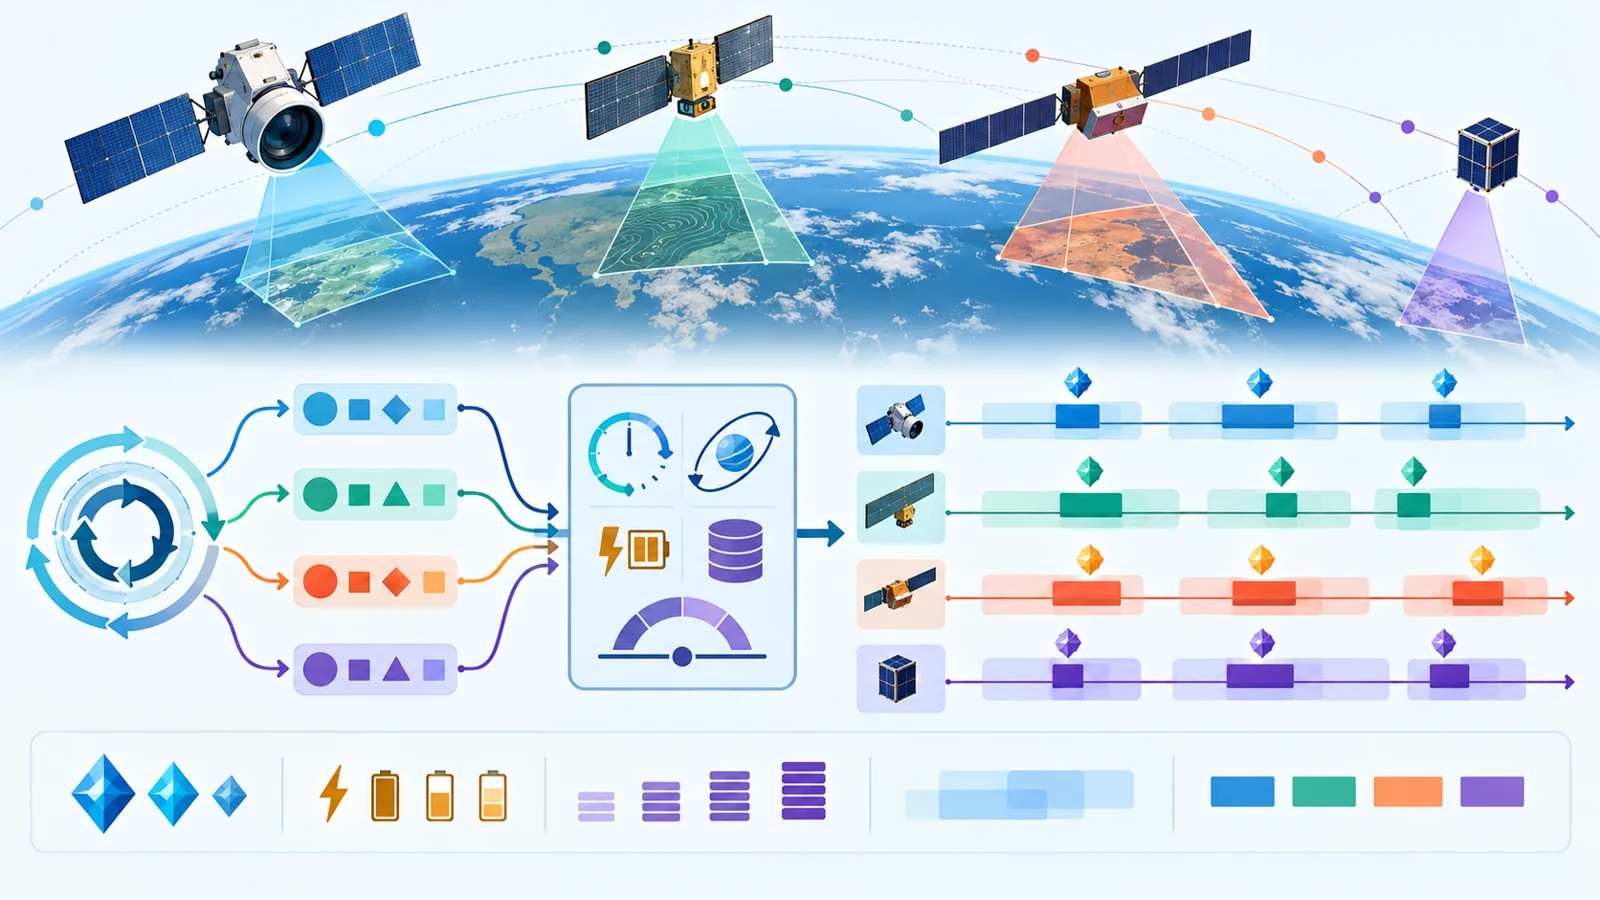
Earth-observation planning becomes difficult when a fleet is made up of satellites that do not behave alike. A task may be visible to one satellite but not another. Even when two satellites can observe it, they may need different attitude maneuvers, consume different amounts of energy, or have different storage limits. A useful schedule therefore has to decide more than which observations are valuable. It must also decide which satellite should perform each task, when the observation can happen, and how the sequence fits with everything else already planned.
An August 25, 2026 arXiv preprint presents a learning-guided way to search through those choices. The study evaluates its method in six constructed heterogeneous satellite scenarios. Its results suggest that software can find schedules with higher preference-weighted utility across the tested cases, while also showing why a better overall score is not the same as improving every scheduling objective at once.
A schedule is a negotiation between access and resources
The scheduling problem in the preprint combines task selection, satellite assignment, observation-window selection, and execution sequencing. Each candidate schedule must respect satellite-specific visibility windows and task time windows, along with conflicts created by the order of observations. Attitude-transition requirements add another layer: moving from one observation to the next can affect whether the sequence is feasible and how much energy it uses. Onboard storage also limits what can be accepted by a satellite.
The satellites differ in orbital access, sensor availability, maneuvering capability, energy budget, and storage capacity. Those differences mean that a task is not a single interchangeable item in the planning process. Its feasible windows and transition costs depend on the platform assigned to it. A schedule that looks attractive when tasks are considered in isolation may become unusable once those satellite-specific details are decoded together.
To keep the search representation compact, the method encodes candidate solutions as task-to-satellite assignment vectors rather than writing out every observation time and sequence directly. A schedule decoder then works out feasible observation intervals and execution orders using the relevant windows, conflicts, maneuvers, and resource limits. The decoder is where the assignment becomes a concrete schedule that can be evaluated.
One score lets planners choose the priority
The preprint combines three normalized utility components: task gain, energy saving, and load balance. Their relative importance is controlled through a preference weight vector. A gain-oriented planning preference can therefore favor valuable observations, while another preference can place more emphasis on conserving energy or distributing work across the fleet.
This arrangement separates two decisions that are easy to blur together. The preference weights express what the planner values in the current situation. The optimization method then searches for an assignment and sequence that performs well under those priorities. The resulting scalar utility is converted into an equivalent cost for the optimizer, with penalties for constraint violations and for feasible tasks left unscheduled.
The benefit of a single interpretable score is operational clarity: the method can return one schedule for a chosen preference instead of only a collection of non-dominated alternatives. But the score remains a tradeoff. A schedule can have the highest weighted utility without leading every individual component. In the main comparison, the reported advantage came mainly from task-gain utility while load balance remained high. Energy-saving utility was not always the best among the methods, which is consistent with a setting where gaining more observation value can justify some additional energy use.
Learning chooses how to search
The reinforcement-learning element does not construct a satellite schedule directly. It acts as an adaptive controller for the evolutionary search. The evolutionary module generates and updates assignment vectors, while an online actor-critic policy observes the search state and selects a high-level operator mode for generating or modifying offspring.
The six modes coordinate different kinds of search activity: warm start, feasibility repair, conflict resolution, local improvement, elite intensification, and diversity rescue. Some actions help the search recover from infeasible assignments. Others refine promising candidates, intensify work around strong solutions, introduce new material, or protect population diversity when the search begins to narrow too quickly.
The controller learns online within each independent run, using feedback from the search rather than an offline training dataset. This keeps the learning task relatively compact because the policy chooses among search modes instead of choosing every task, satellite, window, and sequence position itself. The arrangement also preserves the evolutionary method’s population-based exploration while allowing search behavior to change as the population changes.
Schedule-specific modifications are made before objective evaluation. Each resulting offspring is passed through the shared decoder and evaluated once in the described workflow. That single-evaluation arrangement provides a clear interface between the search operators and the physical-feasibility calculation, and it fits a fixed function-evaluation budget. The budget counts objective evaluations, however; it does not by itself say how quickly a schedule is produced in elapsed time.
What the simulated comparison found
The authors test the method, called RLOSMEA, in six heterogeneous scenarios. The scenarios increase from 100 to 350 candidate tasks and from 5 to 12 agile satellites, enlarging both the assignment space and the interactions among selection, assignment, timing, sequencing, and resources.
The comparison includes AESSPSO, ALNS, GWO, and MemeticEA. All of the compared algorithms obtain feasible schedules in the reported scenarios. For each case, the study summarizes best-so-far weighted-utility convergence over 30 independent runs using mean curves and standard-deviation bands.
RLOSMEA records the highest weighted utility in every tested scenario. The reported curves show that some baselines improve quickly at the beginning but reach a plateau earlier, while MemeticEA is the strongest of the listed comparison methods. RLOSMEA retains a higher final utility across the scenarios, and the relatively narrow variation bands indicate stable run-to-run behavior in these constructed tests.
The component results make the overall score more informative. RLOSMEA’s main edge is in task-gain utility, with load-balance utility also remaining high. That combination suggests the method is finding assignments that capture valuable tasks without concentrating all of the work on a small subset of satellites. RLOSMEA does not always achieve the highest energy-saving utility among the compared methods, so the result is best understood as a stronger overall tradeoff under the selected weights rather than simultaneous dominance on gain, energy, and workload.
The supplied comparisons show the performance of the combined RLOSMEA design. They do not, on their own, isolate how much of the improvement is attributable specifically to the learning controller rather than to the evolutionary backbone, decoder, and schedule-specific operators working together.
Why the result remains a planning result
The six scenarios are constructed simulations, not demonstrations of a schedule being executed by an operating satellite fleet. The reported convergence behavior therefore describes how the algorithms behaved under the study’s modeled tasks, satellite differences, constraints, preferences, and evaluation budget. It does not establish flight deployment, onboard operation, or a realized improvement in an Earth-observation service.
Transfer to mission planning would depend on whether the modeled constraints and preferences capture the conditions that matter in a particular operation. Available planning time would matter as well. A fixed number of function evaluations gives a common accounting basis for comparing the algorithms, but it is not equivalent to a wall-clock deadline and does not establish compliance with one.
The study’s useful contribution is narrower and more concrete: it links an interpretable preference model to a search process that can adapt its operator choices while candidate assignments are being explored. That makes the result relevant to planning-system design, while leaving operational integration and mission-specific acceptance checks as separate questions.
What better scheduling could mean for Earth observation
A mixed satellite fleet could potentially fulfill more valuable observation requests when software can place tasks on the platforms that can actually see them, sequence them around maneuver and resource constraints, and adjust the search toward the priorities mission planners choose. The preprint supports that possibility through higher weighted utility across six simulated scenarios, with the reported advantage coming mainly from task gain while load-balance utility remains high.
The practical benefit would remain conditional. The advantage would need to survive the constraints, data, planning times, and approval requirements of real missions before it could translate into better observation service. The result points toward more preference-aware use of existing satellite resources; it does not promise additional spacecraft autonomy or a realized service improvement.
Key Sources
- Primary source: Reinforcement Learning-Guided Evolutionary Policy Optimization for Preference-Adjustable Heterogeneous Agile Earth Observation Satellite Scheduling
arXiv · Preprint · 2026-08-25