Evidence date · 2025-07-09 · Research note 1 of 3
1 2 3
See current Track status →
One AI configuration answered 91.4% of a set of expert-built questions about the universe correctly. A human expert assessed all 945 answers generated in the test, giving the researchers a reference point for comparing nine retrieval-augmented generation systems—and for checking whether an AI judge could help evaluate answers at a larger scale.
The score is a strong result on a defined test. It does not show that an AI system independently discovered a new result about the universe. The study’s central contribution is a way to compare systems against expert assessments, alongside an early look at whether automated judges can track those assessments.
Questions drawn from cosmology papers
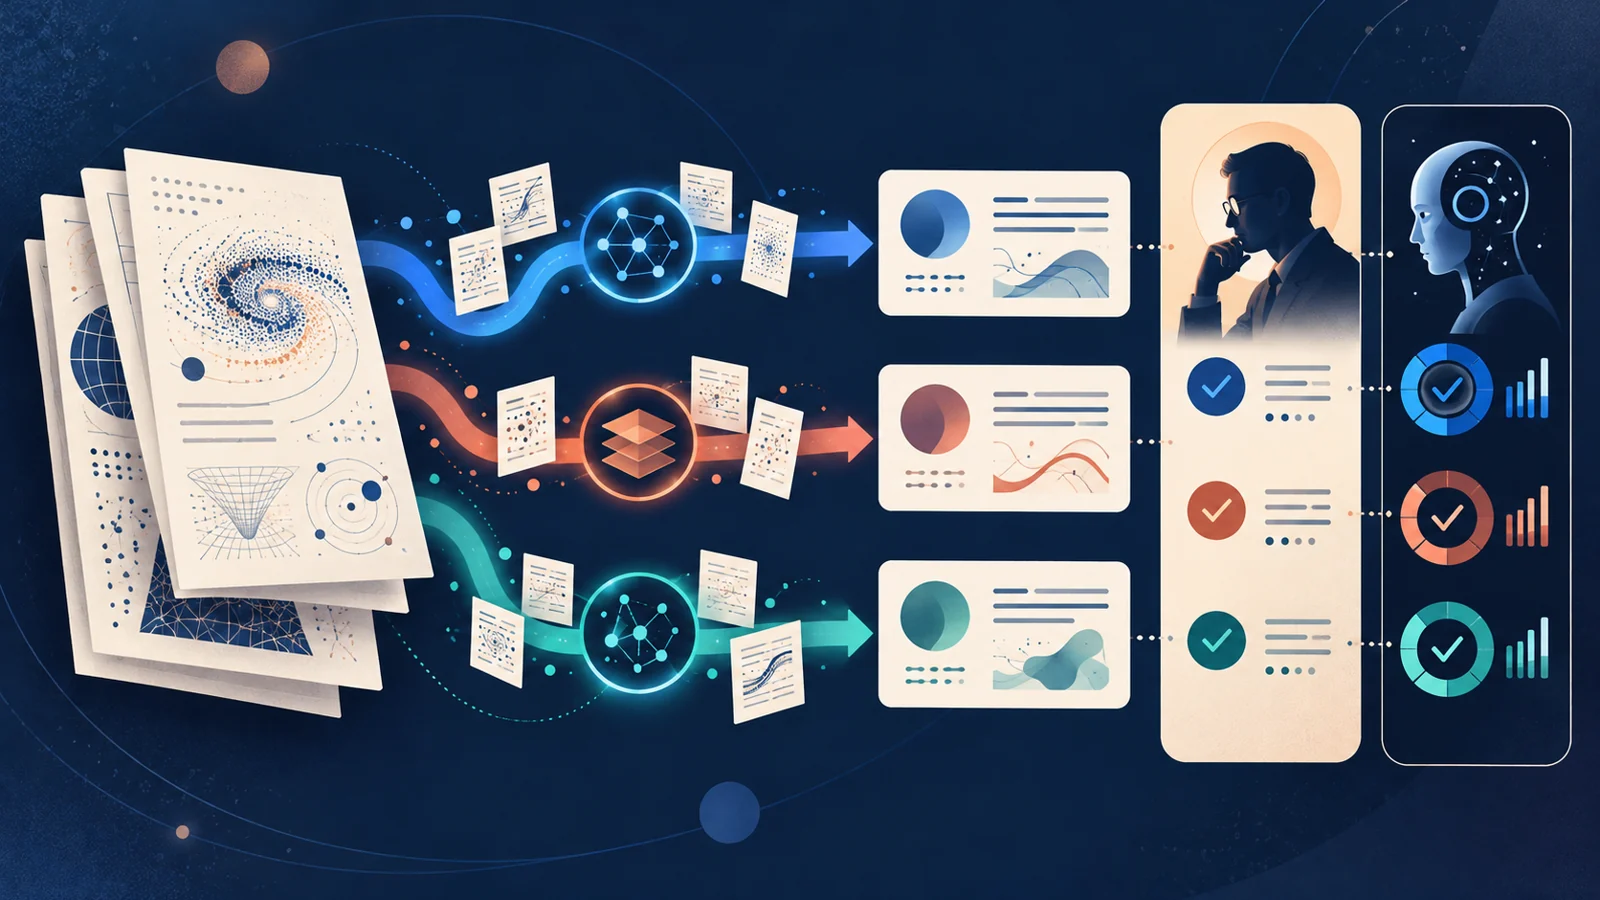
Cosmology is the study of the universe. To test how well AI systems could answer research questions in this field, the authors created CosmoPaperQA, a set of 105 question-and-answer pairs based on five highly cited cosmology papers. Expert cosmologists developed and checked the questions, which were designed to resemble inquiries that could arise from research rather than generic trivia.
The questions covered different kinds of work: retrieving a specific fact, bringing information together from more than one piece of evidence, and interpreting material that calls for domain knowledge. The study used the same question set to assess nine system configurations. Each system’s 105 answers were judged by a human expert, for 945 assessments in total.
That design gives the comparison a meaningful human reference, but its reach is bounded by the five papers and the particular questions chosen. The benchmark tests answers to a curated set of research questions; its score should be read in that context.
How the systems searched before answering
Retrieval-augmented generation, or RAG, pairs a language model with a search step. The system looks through external documents for material relevant to a question, then uses what it finds to compose an answer. Here, the researchers compared different ways of preparing cosmology papers, finding relevant passages and generating responses.
Their SciRag framework brought several RAG systems into a shared evaluation. The paper-processing pipeline used optical character recognition, a technique for turning material in documents into machine-readable content, to handle features such as tables, figures, equations and specialized notation. It produced formats intended to work across different RAG systems.
Search strategies varied too. Some configurations used semantic search, which looks for passages related in meaning to a question. The strongest approach combined automatic query rewriting, parallel searches, keyword and semantic search, and reranking to prioritize retrieved results. The authors report that this approach outperformed simpler semantic-only retrieval in the tested hybrid systems.
These differences matter because an answer depends partly on what the system retrieves. A fluent response can still be wrong if the relevant passage is missed or the retrieved material does not support the answer. The benchmark compared the complete tested configurations, so the accuracy figures reflect their combined search and answer-generation setups.
The best score came with a cost tradeoff
The leading commercial configurations scored between 86.7% and 91.4% on human evaluation. OpenAI Assistant configurations reached 89.5% to 91.4%, with the top result coming from OpenAI embeddings and a generative model. VertexAI Assistant reached 86.7%.
Two other configurations scored 85.7% and 84.8%, close to VertexAI Assistant’s 86.7%. PaperQA2, an academic tool, scored 81.9%. These results show that the leading system was not the only one to answer most questions correctly on this benchmark.
Accuracy was not the only consideration. The authors report that VertexAI offered better cost-efficiency, while OpenAI achieved the highest accuracy at greater operating cost. They do not give a universal winner for every research task: the preferable configuration would depend on how much accuracy matters relative to operating cost, and on the papers and questions being handled.
A judge can rank systems well and still overrate answers
Human review is useful for checking scientific answers, but reviewing many systems across many questions takes expert time. The researchers therefore calibrated large language models to act as judges of answer quality, comparing their assessments with the human evaluations.
The judges largely preserved the human-based ordering of the systems. Across three evaluation methods, the reported ranking correlations were above 0.99. In other words, the systems that scored higher with the human evaluator tended to rank higher with the AI judges too.
That agreement in ranking did not mean every judge gave accurate absolute scores. The Gemini judge rated some systems 5 to 15 percentage points above the human evaluation. For one configuration, the Gemini judge gave a score of 27.6%, versus 16.2% in the human evaluation. The OpenAI judge was more conservative in the reported comparisons, offering a lower estimate of performance.
This gap matters if researchers want to use automated judging to assess thousands of answers. A judge that reliably orders systems could help identify promising configurations, but inflated scores could make answer quality look better than it is. Calibration against expert judgments helps reveal that difference before relying on an automated judge at larger scale.
The paper-title clue narrows the test
Many benchmark questions explicitly named the paper they referred to. That choice helped create questions grounded in real research, but it also gave systems a clue about where to look. The test therefore says more about answering questions when the relevant literature is identified than about finding the right work across a much larger collection without guidance.
That boundary changes how to interpret the 91.4% result. A future test with more papers and naturally worded questions that omit paper titles could show whether systems can locate relevant evidence as well as explain it. The July 2025 preprint provides a first measured comparison for its curated set; it does not demonstrate autonomous discovery or establish a best setup for all astronomy research.
The authors made the question set, human evaluations, RAG pipelines and AI-judge system available for further work. Those materials give researchers a way to examine and extend the comparison, including whether the judges’ rankings and absolute scores remain reliable as the test grows.
What this could change
An astronomer checking a new claim about the universe might one day ask an assistant to find relevant papers and compare what those papers say. If systems can retrieve the right evidence and give dependable answers—and if their reliability can be checked against expert judgments—the assistant could help researchers spend more of their attention interpreting evidence. This study did not demonstrate that workflow; it tested answers to questions built from a small, identified collection of papers.
A useful next milestone would be a larger cosmology benchmark with human-graded answers and fewer clues about which papers to consult. If calibrated AI judges still track both system rankings and answer correctness on that broader test, researchers would have stronger grounds to use them when evaluating far more answers than experts can review individually. That would make it more practical to assess research assistants at scale before depending on them to search across the literature.
Key Sources
- Primary source: Evaluating Retrieval-Augmented Generation Agents for Autonomous Scientific Discovery in Astrophysics
arXiv · Preprint · 2025-07-09